
Half-day working workshop · Manchester, UK
Do Androids Dream of Electric Papers?
Benchmarking AI Scientists - Frameworks, Datasets & Environments
“How do we know when an AI Scientist is doing science?”
A half-day working workshop bringing together researchers and practitioners to develop shared approaches to benchmarking AI Scientists – not only what they discover, but how.
Application deadline: 16 October 2026 · Places are limited
Date
Duration
Format
Location
About the workshop
How do we know when an AI Scientist is actually doing science?
AI Scientists — systems that formulate hypotheses, design and run experiments, interpret results, and iterate with limited human intervention — are developing rapidly, but the field still lacks a shared way to evaluate and compare them. Different teams currently work with different tasks, datasets, environments and metrics, making cross-system comparison and cumulative progress difficult.
Our starting point: a credible benchmark can not evaluate only whether an AI Scientist reaches the right answer — it must evaluate how the result was produced. “Do Androids Dream of Electric Papers?” is a focused working workshop that breaks this central question into six that any credible benchmark has to answer:
1.
What should we test?
Tasks & capabilities
2.
Where should it do it?
Environments
3.
What should we observe?
Traces & provenance
4.
How should we score it?
Metrics
5.
How do we know the result is real?
Reproducibility & contamination
6.
How do systems compare?
Benchmark protocol
The workshop explores two tracks
Track A
Evaluation Framework
What should we test, how should we score it, how do systems compare? This track works on the task taxonomy, the metric primitives – correctness, provenance coverage, trust-closure, time-to-result, reproducibility and human-in-the-loop accounting – and the reporting protocol that makes results from different systems comparable.
Track B
Datasets & Environments
Where should it do it, what should we observe, how do we know the result is real? This track works on the shared infrastructure a credible benchmark requires: curated scientific corpora with provenance, ground-truth discovery tasks, simulated and instrumented experimental environments, annotated discovery traces, and the contribution formats, licensing and contamination governance that keep them trustworthy.
the discovery trace
Where the tracks meet
Environments produce it; evaluation runs on it. A shared trace format – what is recorded, at what granularity, with what provenance – is the interface between the two tracks, and the point at which the two working groups will converge.
Constructor Knowledge Labs and ARIA will seed the discussion with a cross-project testbed spanning neuromorphic materials, electrocatalysis, antibiotics, crystal generation and detector co-design, together with a candidate metric scaffold for the community to challenge and improve.
Expected outcomes
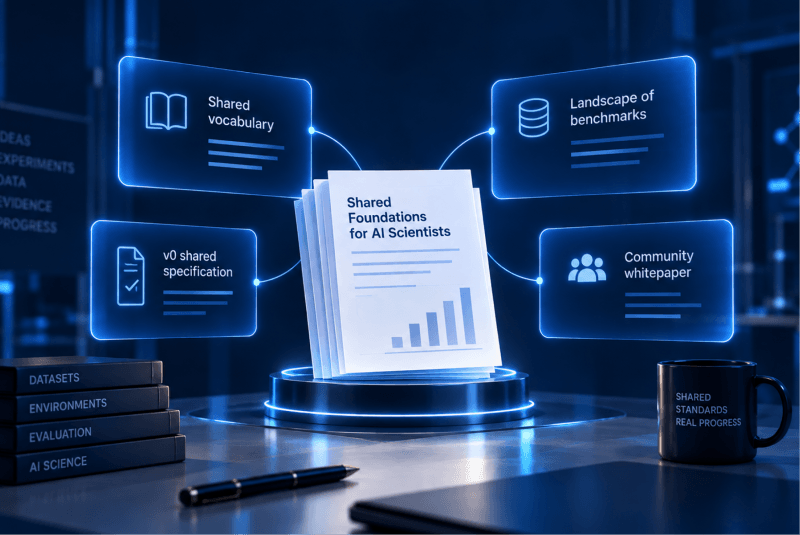
The workshop aims to produce first shared answers to these six questions, in the form of:
- A shared vocabulary for benchmarking AI Scientists.
- A landscape of existing benchmarks, datasets, environments and evaluation approaches.
- A v0 shared specification, including a candidate task suite, metric primitives, a discovery trace format and dataset/environment contribution protocol.
- An initial outline for a community whitepaper structured around the six questions, with opportunities for participants to contribute after the workshop.
Who should attend
Researchers and practitioners building, evaluating or providing the infrastructure for AI Scientist systems
We invite researchers and practitioners who build, evaluate or provide the data and environments for AI Scientist systems, including those working on:
The workshop is deliberately practitioner-heavy, and particularly welcomes teams that define scientific tasks, build evaluation systems, develop datasets or environments, or work directly on autonomous scientific discovery.
Call for participation
Apply to participate
Workshop Participant
Lightning Talk + Workshop Participant
Key dates
Important dates
Programme · 25 November 2026 · 09:30–15:45 GMT
The day is built to converge
09:30
Arrival, Coffee & Get-together (30 min)
10:00
Welcome & Framing (10 min)
CKL × ARIA introduction: why benchmarking is a bottleneck for AI Scientists, the two problems in scope – evaluation frameworks and datasets/environments – and the candidate scaffold for discussion.
10:10
Invited Keynote + Q&A (40 min)
A frontier perspective on evaluating AI Scientists: what should be measured, and what shared datasets and environments does the field need?
10:50
Lightning Talks (60 min)
8–10 teams, each giving a 5-minute presentation + brief Q&A on their AI Scientist benchmark, evaluation harness, dataset, environment or related work. (A short CKL × ARIA testbed presentation will be included as one of the contributions.)
11:50
Coffee Break (20 min)
Informal discussion and cross-team comparison.
12:10
Parallel Working Sessions (60 min)
Each track works from the seed scaffold towards its part of the v0 specification and ends with a one-page summary to bring into the convergence session.
Track A – Evaluation Framework: what should we test, how should we score it, how do systems compare?
Task taxonomy, metric primitives — correctness, provenance coverage, trust-closure, time-to-result, reproducibility and human-in-the-loop accounting — and the reporting protocol for comparing systems.
Track B — Datasets & Environments: where should it do it, what should we observe, how do we know the result is real?
Shared corpora, ground-truth discovery tasks, simulated/instrumented environments, annotated traces, contribution formats, licensing, leakage/contamination and provenance governance.
13:10
Lunch Break (Lunch will be provided by the organizers) (45 min)
13:55
Convergence: Drafting the v0 Specification (60 min)
The two tracks will converge on a v0 shared specification covering tasks, environments, traces, metrics, reproducibility and comparison protocols.
14:55
Closing & Whitepaper Next Steps (10 min)
Timeline for the whitepaper, how to contribute tasks, datasets, environments and traces, and how the v0 specification will be circulated for comment.
15:05-15:45
Informal discussion / Networking
Keynote Speaker
To be announced.
Organizing Committee
Andrey Ustyuzhanin
Mariia Snigireva
Apply to Participate
Help build the shared benchmark for AI Scientists
Places are limited. Applications are open to both general workshop participants and applicants wishing to give a 5-minute lightning talk.
Application deadline: 16 October 2026